One line of code / Amazon's open-source bet against the CUDA moat
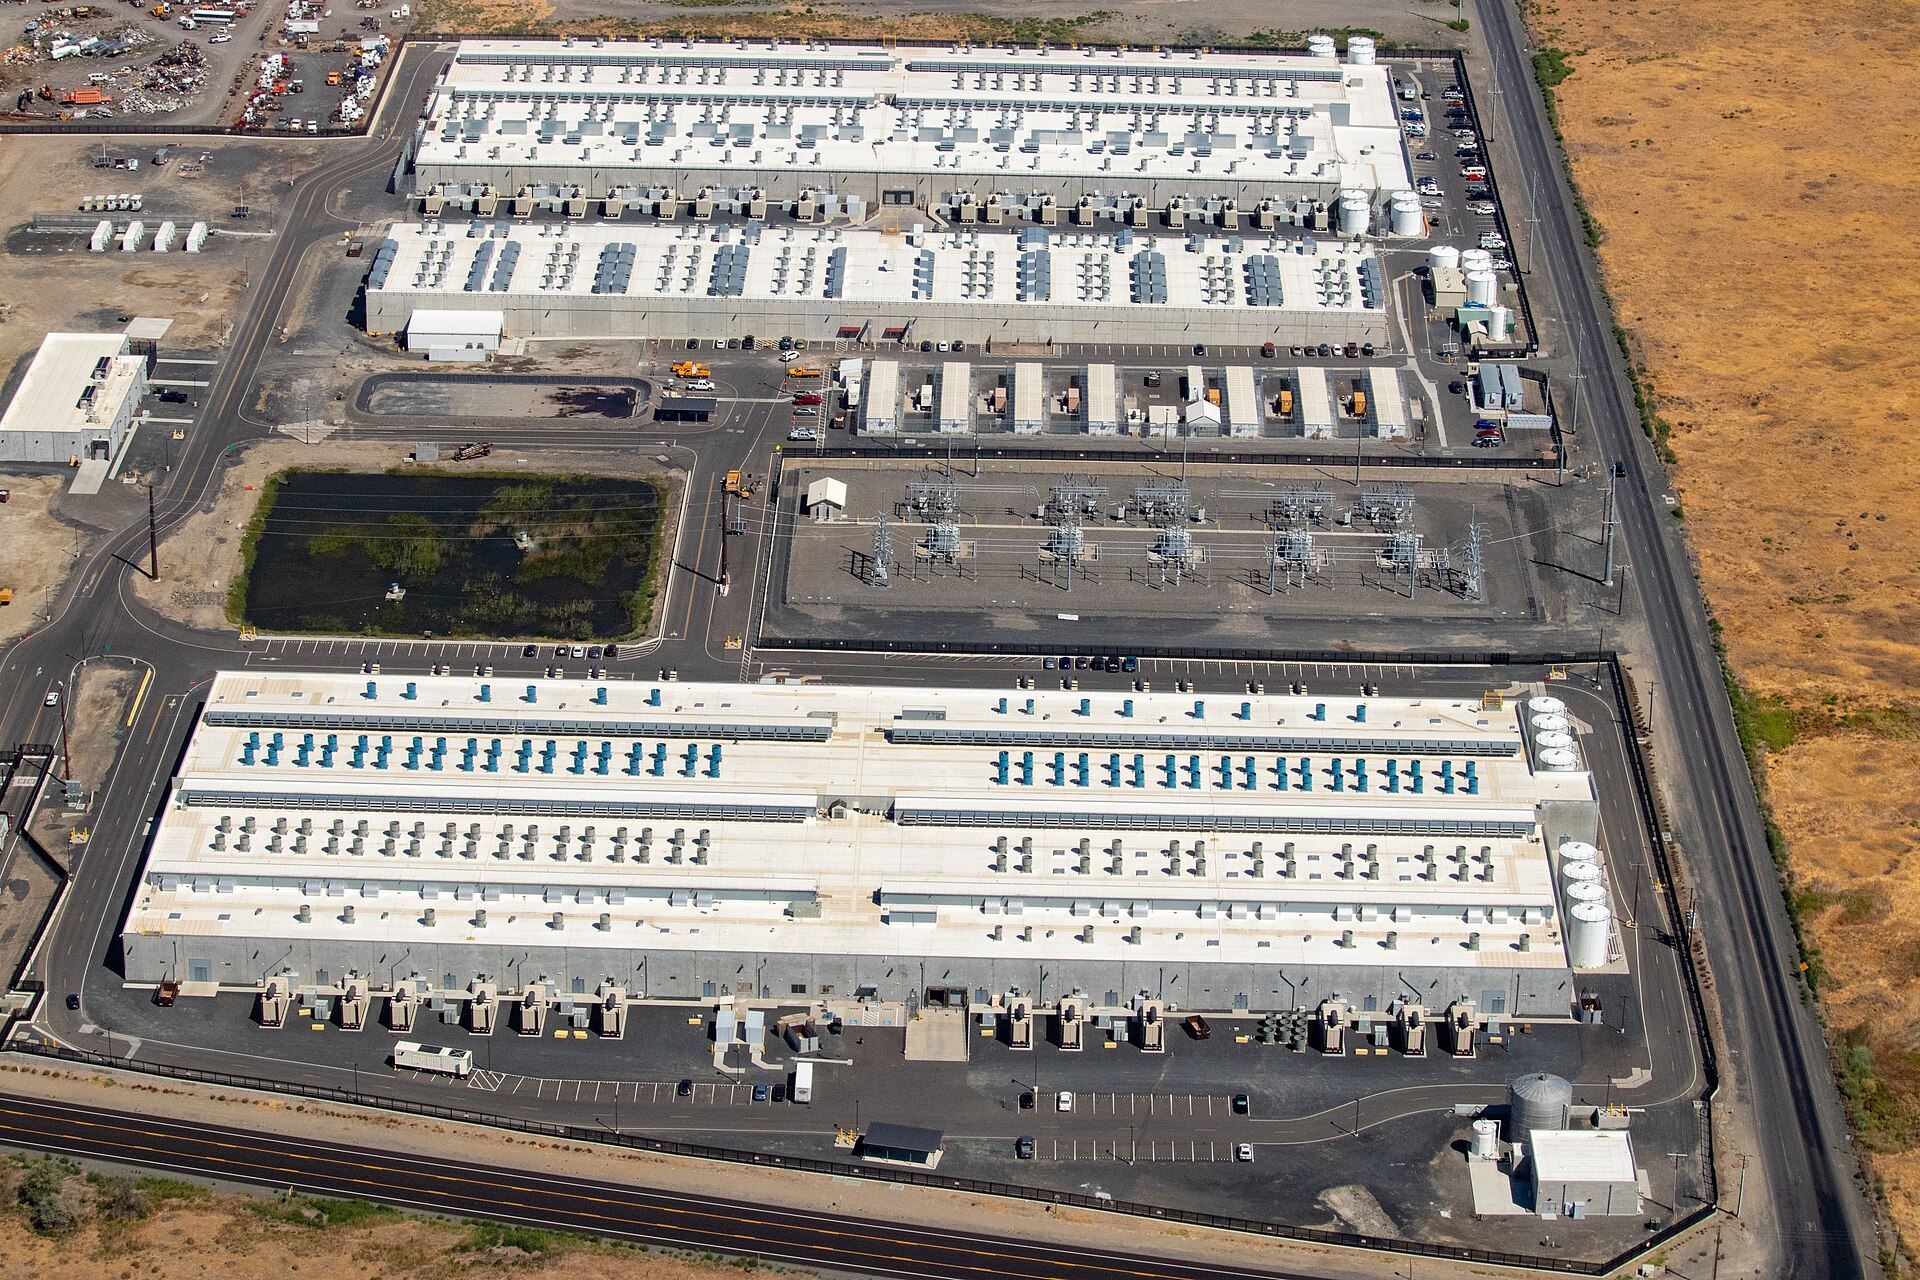
What TorchNeuron actually does
PyTorch is the default language of modern AI development: researchers prototype in it, startups train in it, and most open-weight models are released in it first. Historically, that code has run best — and often only — on Nvidia graphics processors, because Nvidia spent nearly two decades building CUDA, the software layer that connects frameworks like PyTorch to its silicon. Moving a working PyTorch model to a rival chip has usually meant weeks of engineering: rewriting kernels, revalidating outputs, and accepting performance surprises along the way.
TorchNeuron attacks exactly that friction. According to Amazon, a developer points existing PyTorch code at Trainium by changing one configuration setting, and the tool handles the translation underneath. Colin Brace, an Amazon software vice president involved in the effort, framed the pitch in workflow terms: the tool reduces the number of steps required to try Amazon's chips, and it is designed to fit the way AI teams already build rather than asking them to adopt a new stack today in order to save money later. That sequencing matters more than it might appear. Almost every previous challenger to Nvidia has led with price or raw performance and asked customers to pay an engineering toll up front. Amazon is trying to make the toll disappear first, and to argue about price second.
The real target is CUDA, not silicon
It is worth being precise about what Nvidia's advantage actually is, because TorchNeuron only makes sense once you see it clearly. Nvidia's chips are excellent, but chips can be matched — Amazon, Google, AMD and a dozen startups all field credible AI silicon. What has proved nearly impossible to match is CUDA: the libraries, debugging tools, documentation, university courses and muscle memory accumulated around Nvidia's platform since the mid-2000s. A chief technology officer choosing a rival chip is not really choosing hardware. She is choosing to retrain her engineers, rewrite her tooling and accept unknown failure modes in production — and she usually declines. That is why Nvidia has kept the overwhelming share of AI training even when rivals undercut it on price, a dynamic we examined in our coverage of Amazon's own complicated dependence on Nvidia chips.
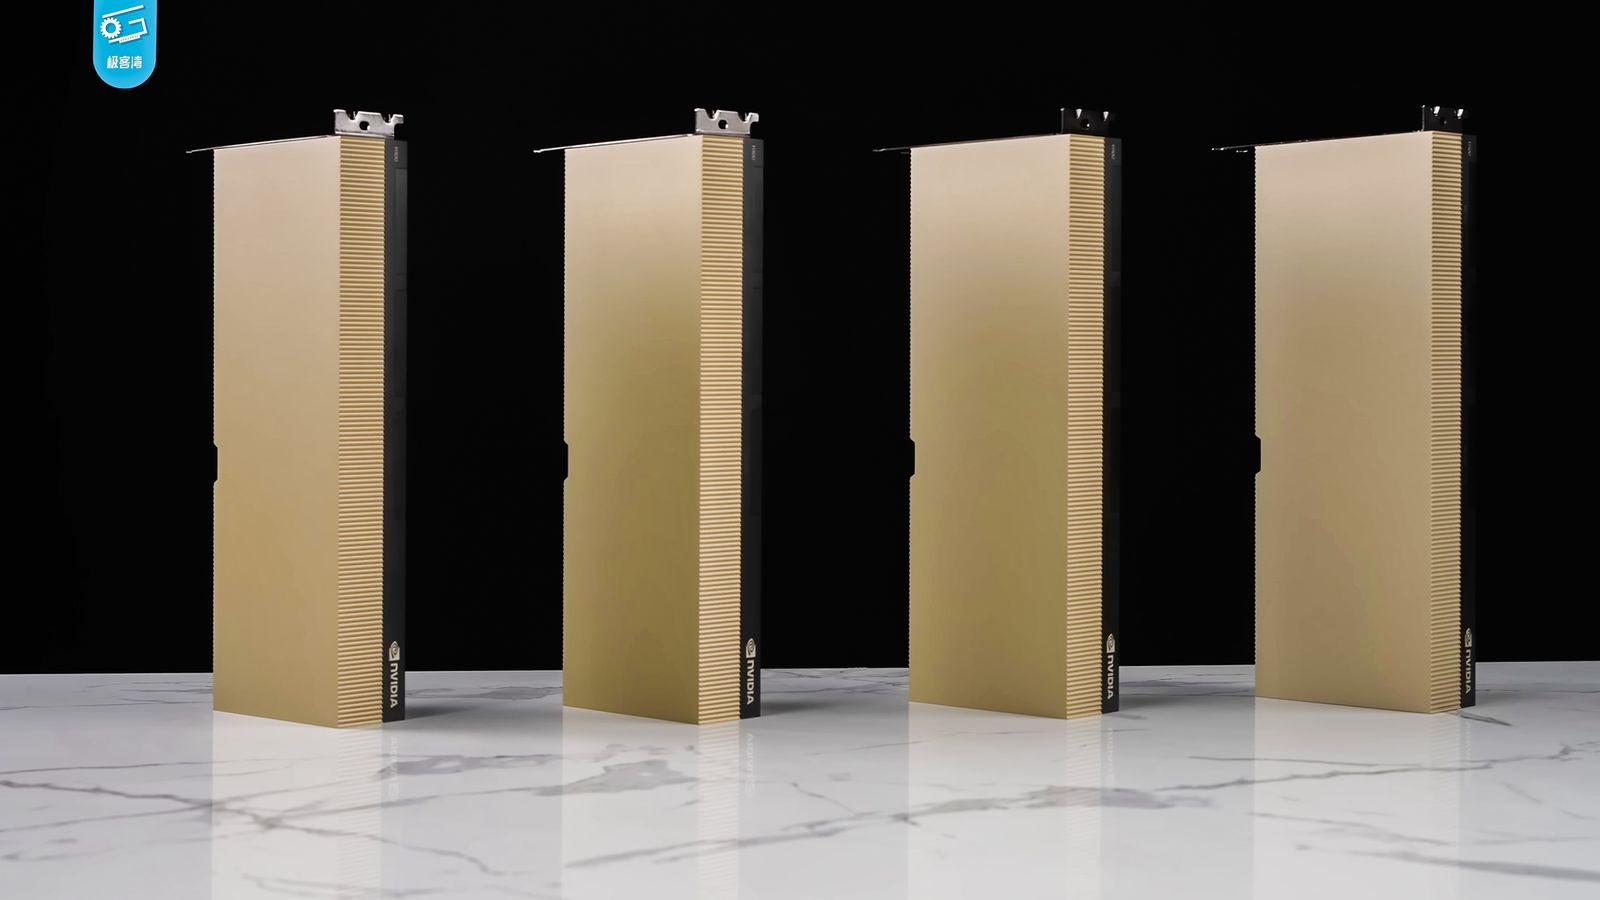
TorchNeuron's wager is that PyTorch itself has become the layer developers are loyal to — and that if the framework becomes truly portable, loyalty to the chip underneath it weakens. If the same PyTorch code runs acceptably on Trainium, the hardware decision collapses back to the things Amazon likes competing on: price, availability and integration with the rest of AWS. Amazon says switching to its chips can reduce costs, which is the expected claim from any challenger. The tool is what makes that claim cheap enough to test.
Thirty early customers, in telling categories
Amazon says more than 30 early customers are already using TorchNeuron, concentrated in robotics, world models and voice AI. The categories are more informative than the count. Robotics and voice teams run inference-heavy, cost-sensitive workloads where a cheaper chip pays for itself quickly, and where a failed experiment does not take down a flagship training run. World-model teams — building systems that simulate environments in which other AI systems are trained — consume compute in bursts and are chronically hungry for capacity wherever they can find it. In other words, the early adopters are precisely the users for whom trying Trainium was already tempting and the switching toll was the obstacle: the persuadable middle of the market, not the frontier labs whose CUDA dependence runs deepest.
The launch choreography reinforces the point. Releasing TorchNeuron free, as open source, at the PyTorch Conference in San Jose on October 20 is a distribution strategy, not a courtesy. It puts the tool in front of the community whose habits decide AI hardware choices, and it removes the two easiest objections in advance: the tool costs nothing, and it asks for almost nothing. Open-sourcing it carries a further implication Amazon is surely aware of — if outside developers contribute to TorchNeuron, it stops being an Amazon product pitch and starts becoming shared infrastructure, which is much harder for an incumbent to argue against.
The missing numbers
Honesty requires stating plainly what Amazon has not provided: independent benchmarks. As of the announcement, Amazon has published no third-party-verified figures showing how Trainium performs against current Nvidia hardware on real production workloads — tokens per second, cost per training run, energy per inference — under TorchNeuron. "Runs with one setting changed" and "runs as fast, at lower total cost, at production scale" are different claims, and only the first has been demonstrated in public so far.
The migration risk is also real even when the code ports cleanly. Production AI systems tend to fail in the seams: a numerical edge case in one kernel, a debugging tool that does not yet exist on the new platform, a performance cliff on one unusual model shape. Teams that move workloads will discover Trainium's maturity — or its gaps — in ways no launch announcement can settle. That is not an argument against trying; a free, one-setting trial is exactly how such questions should be answered. It is an argument for treating the launch as the start of an experiment rather than its result — the same caution that applies to rivals such as Microsoft's Maia 300 effort to loosen Nvidia's grip, where the silicon arrives first and the ecosystem verdict arrives years later.
Why this matters
Start with the background, because Amazon has run this play before. Annapurna Labs, the Israeli chip-design house Amazon acquired in 2015, first produced networking and storage silicon, then Graviton — the Arm-based server CPUs that gradually persuaded AWS customers to move ordinary computing off Intel and AMD. Graviton did not win by being dramatically faster than the incumbents it displaced. It won by being good enough, cheaper, always available inside AWS and — crucially — easy to try: for many workloads, moving was a recompile and a test cycle. Trainium is the same strategy applied to AI, and TorchNeuron is the "easy to try" layer that strategy was missing. A company that designs the chip, owns the cloud, controls the framework tooling and can price the whole bundle together has structural advantages that no standalone chip startup can copy.
Who wins and who loses follows from that structure. If TorchNeuron works as advertised, the winners are AWS customers with portable PyTorch workloads — and their bargaining power against Nvidia's pricing improves even if they never move a single job, because a credible exit option disciplines an incumbent's prices all by itself. Amazon wins twice over: Trainium adoption rises, and AWS becomes harder to leave. The clearest loser is the assumption underneath Nvidia's valuation — not that its chips are the best available, but that its software moat makes "best" permanent. Nvidia would not need to lose many workloads for that assumption to crack. It would only need a few respected labs to demonstrate, publicly and with numbers attached, that the exit door is unlocked.
The critics' case deserves equal weight. Sceptics note that translation layers have a long history of working beautifully on demonstrations and unevenly on the long tail of real models — and that Nvidia's deepest advantage may not be CUDA's code at all, but the thousands of engineers who have debugged on it for a decade. There is also a quieter conflict of interest worth naming: AWS is one of Nvidia's largest customers, and Amazon profits handsomely from renting Nvidia capacity to the same AI teams TorchNeuron courts. A tool that genuinely shifted demand to Trainium would cannibalise some of that business — which is either evidence of Amazon's seriousness, or a reason to doubt how hard it will push. The same week's news underlines how many directions the anti-CUDA bet is now being placed from: on the same day, investors valued the open-architecture chip startup Tenstorrent at $6.2 billion, as we report in our coverage of Tenstorrent's $6.2 billion funding round. The moat is being attacked with cloud tooling on one side and open silicon on the other.
The data, such as it is, supports only a narrow conclusion for now. Thirty-plus early customers across three workload categories is a meaningful pilot — larger than a demo, far smaller than a migration. One configuration setting is a genuinely new fact about switching costs, if it holds outside Amazon's own test cases. And zero independent benchmarks is a genuinely missing fact, which no amount of launch-day enthusiasm should paper over.
What happens next
The test is easy to state and hard to fake: which AI labs publicly move real workloads onto Trainium through TorchNeuron, and report measured cost or performance gains with their names attached? Watch three signals over the coming months. First, named production case studies with numbers — not logos on a slide, but engineering blog posts with before-and-after figures. Second, whether the PyTorch community embraces the tool: outside contributions and integrations would show it becoming infrastructure rather than marketing. Third, Nvidia's response — if CUDA's stewards suddenly invest in making PyTorch portability a selling point of staying, that in itself will tell you the threat registered.
Software decided the last era of computing more often than silicon did. The AI era has so far been an exception, ruled by one company's hardware and the software welded to it. TorchNeuron is Amazon's argument that the exception is ending — that the framework, not the chip, is where loyalty now lives. The October 20 release starts that argument. The benchmarks, when someone independent publishes them, will finish it.
Sources: Binance Square, Oct. 20, 2026, reporting the Reuters-syndicated announcement of Oct. 19 (Annapurna Labs; one configuration setting; Colin Brace comments; 30+ early customers in robotics, world models and voice AI; planned free release Oct. 20 at the PyTorch Conference, San Jose); The Daily Fathom, Oct. 20, 2026 (CUDA lock-in analysis; absence of independent benchmarks; production migration risk). Related on Signal Post News: Amazon, Nvidia chips and the investors caught between them · Microsoft's Maia 300: another cloud giant builds its own Nvidia rival · Tenstorrent's $6.2 billion valuation funding round.